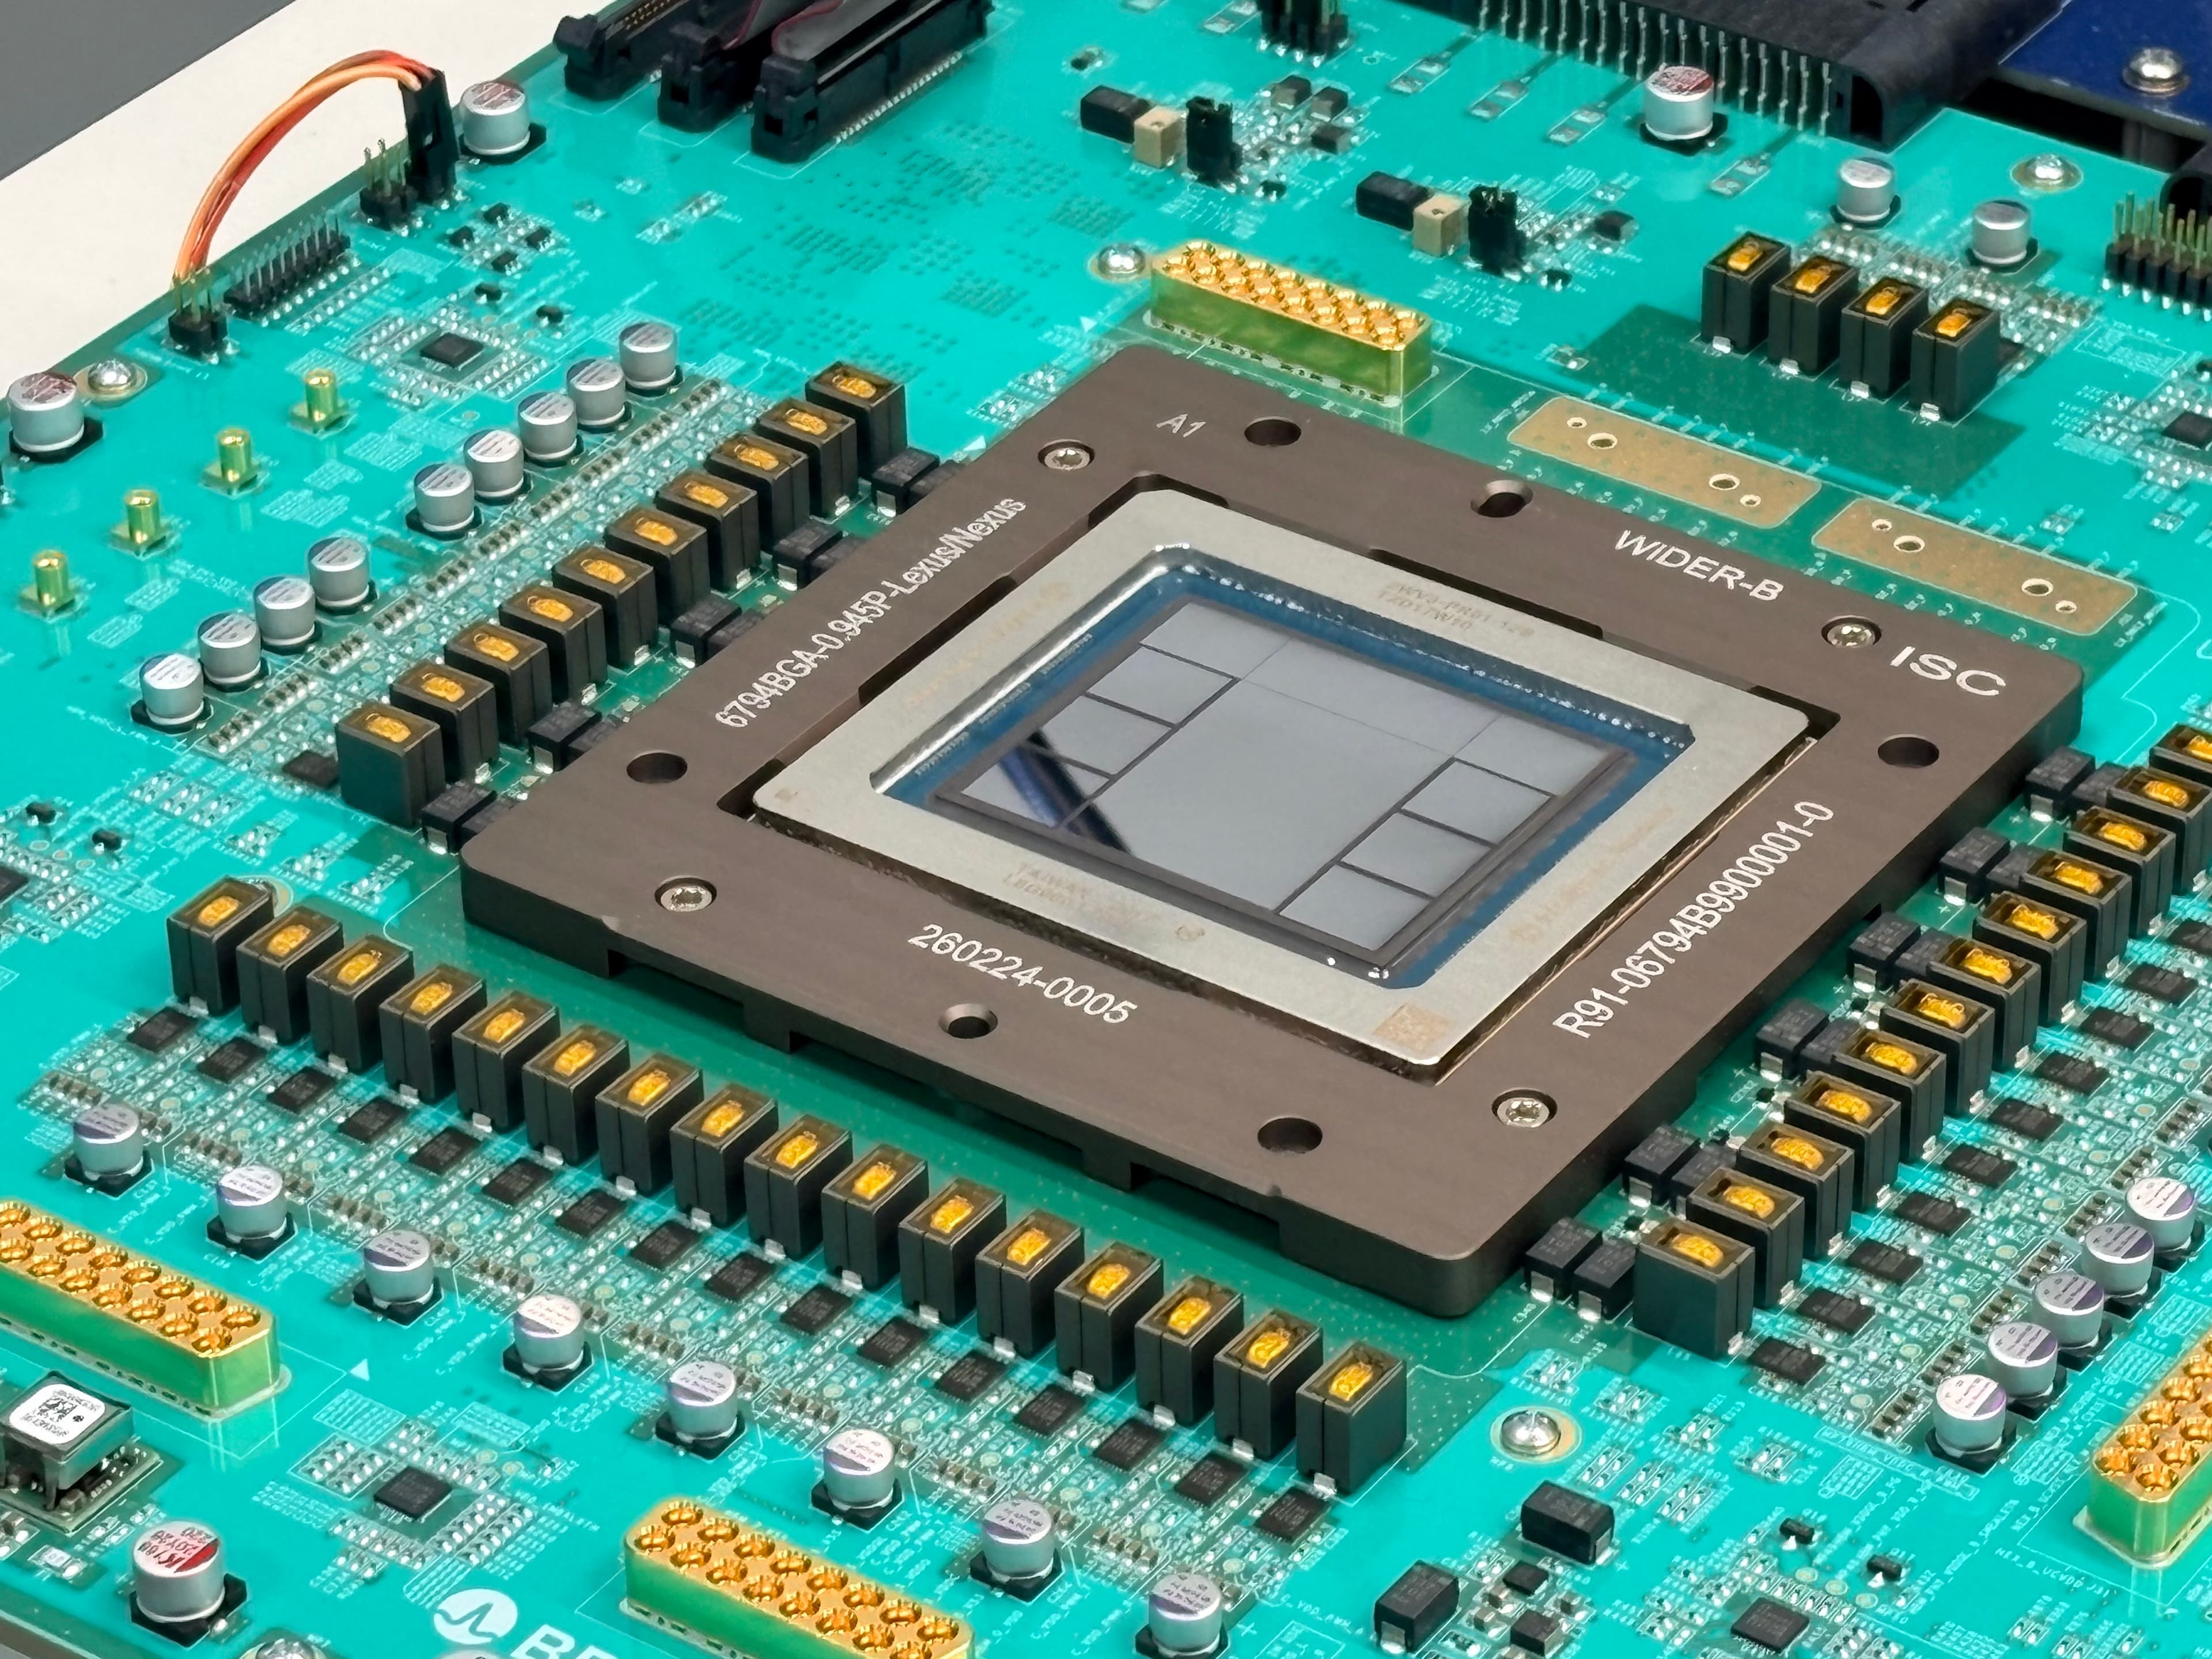
Jalapeño's first results show industry-leading speed and efficiency in AI inference
This is an infrastructure announcement about how OpenAI runs its models more efficiently, not a new feature you'll see directly in ChatGPT. Over time, faster and cheaper inference can mean quicker responses and potentially lower costs for anyone building on OpenAI's API.
What changed
Source summary
OpenAI announced first results from Jalapeño, its first custom-built AI inference chip, showing 1.5-1.9x more AI work per watt and 1.7-3.6x lower latency versus its prior infrastructure, measured on the public InferenceX benchmark across GPT-OSS 120B, DeepSeek R1 and Kimi K2.5 models. OpenAI plans to deploy it in production within its own infrastructure by the end of the year.
Why it matters to your work
Practical interpretation
This is an infrastructure announcement about how OpenAI runs its models more efficiently, not a new feature you'll see directly in ChatGPT. Over time, faster and cheaper inference can mean quicker responses and potentially lower costs for anyone building on OpenAI's API.
When this could help
Useful context when assessing OpenAI's infrastructure roadmap, capacity planning, or when comparing inference efficiency claims across model/chip providers rather than for any direct developer action today.
OpenAI's first custom inference chip, Jalapeño, shows it can serve meaningfully more AI work per watt at lower latency than its prior infrastructure, which over time should translate into faster responses and more available capacity for OpenAI's own products.
What to check
- Jalapeño is not yet in production; figures are first-results benchmark comparisons, not live production performance. Reported efficiency gains were 1.5-1.9x more AI work per watt and 1.7-3.6x lower end-to-end latency versus OpenAI's prior infrastructure, with some block-level optimisation figures applying to selected blocks rather than the full model. Source ↗
Sources & provider guides
Official documentation checked 12 Oct 2026. SCALA prompts and workflows are suggestions, not claims of hands-on testing.
Source & availability
This is a summary of a published provider announcement, with practical context from SCALA’s feed.
Plan, region, workspace and rollout conditions may affect access in Australia. Check the original source for current availability.
openai.comThis update is primarily for technical teams.